Showing posts with label privacy. Show all posts

Sunday, February 19, 2017

Differential privacy


These days one reads a lot about the right to privacy. But what is it and how does it differ between the real and the digital description of the world? Briefly, it is a person's right to have and more importantly maintain control over information about oneself, which is fundamental to human's freedom of self-determination. In the digital context one seemingly lost this right in favor of using free services, handy tools that satisfy people's urge to communicate with each other and stay in touch and up-to-date at all times. Since more and more people realize that behind such apps and web pages naturally there are business models, society increasingly demands to reclaim control over collected personal data, which has been provided, unsolicited or involuntarily, to online merchants or telephony service providers at the time of use, for example. On the other hand collecting user information in databases is crucial as corporations offering named services see it. In order to make good products, tailored recommendations, and especially in the age of big data and machine learning, precise predictions by evaluating various functions on the data.

Statistical database queries have been studied quite some time now, and in fact it turns out that often it is sufficient to allow query access only to a population's aggregate data, not individual records, to derive useful statistics and achieve desired functionality! A common approach is to merely allow aggregate queries (i.e. range, histogram, average, standard deviation, ...) and rather than returning exact answers about sensitive data fields to specify intervals or give imprecise, statistically noisy counts.

You might have asked yourself, don't cryptographic techniques that have been omnipresent in this blog such as FHE (Fully Homomorphic Encryption) or secure MPC (Multi-Party Computation) solve this problem? Wouldn't it be possible to encrypt the user data yet for the service provider to compute useful statistics on it?
Indeed, it could be realized with the general FHE, MPC toolkit, but currently it is inefficient to operate them at that scale in practice, such that statistics over huge quantities of data are useful to infer statements about a given database. Hence specific, more slender tools have been designed to overcome this gap. Whereas FHE avoids a trusted 3rd party to compute (i.e. arbitrary functions or sophisticated statistics) on users sensitive data, here typically one explicitly allows a trusted 3rd party to collect and aggregate data in a privacy-preserving fashion. Users might do so i.e. when installing an app and argue to have an advantage for themselves like good default settings, an overall performance gain; or it might be a requirement to share information in order to use the service for free in the first place.

Differential privacy (often abbreviated DP) is a framework for formalizing privacy in statistical databases. It can protect against so called de-anonymization techniques that try identifying an individual record by linking two separately released databases that have been stripped off (quasi-)identifiers and look innocuous. Especially apriori knowledge or known partial history can be leveraged to derive more information from a released "anonymized dataset" other than the purpose it was originally intended to serve.

Let's look at a mathematical definition that captures and formalizes the notion of privacy and which has been studied in cryptography in the past 10 years. Let $d,n$ be a positive integers and $f: X^n \rightarrow \mathbb {R} ^{d}$ some statistics on a database comprised of $n$ records.

An algorithm $\mathcal {A}: X^n \rightarrow \mathbb {R} ^{d}$ that computes $f$ is said to have the $(\epsilon, 0)$-differential private attribute or ($\mathcal {A}$ is $\epsilon$-DP, for short) if for all neighboring subsets of a given database $x_{1} \neq x_{2}$ and $x_{1} \sim x_{2} := x_{1} \sim_1 x_{2}$ (they differ in just 1 element), and all subsets $S \subseteq \mathbb {R} ^{d}:$
\begin{align}
\mathbb{P}[\mathcal{A}(x_{1})\in S]\leq e^{\epsilon } \cdot \mathbb{P}[\mathcal{A}(x_{2})\in S]
\end{align}
holds. Looking more closely at this definition $\forall x_{1}, x_{2} \in X^n, x_{1} \sim x_{2}:$
$$\mathbb{P}[{\mathcal{A}}(x_{1})\in S]
\leq e^{\epsilon } \mathbb{P}[{\mathcal{A}}(x_{2})\in S] \Leftrightarrow \frac{\mathbb{P}[{\mathcal{A}}(x_{1})\in S]}{\mathbb{P}[\mathcal{A}(x_{2})\in S]} \leq e^{\epsilon }\\ \Leftrightarrow \log \left(\frac{\mathbb P[\mathcal{A}(x_{1})\in S]}{\mathbb{P}[{\mathcal{A}}(x_{2})\in S]}\right) \leq {\epsilon}$$
we can identify the so called "privay loss" of an algorithm (or in this context often called mechanism) $\mathcal {A}$. In this setting $\epsilon$ can be called the privacy budget. In less exact terms it captures the following: By specifying the privacy budget, it is possible to control the level of privacy and make an algorithm respect this additional constraint by techniques introduced below.
For those familiar with the concept of max-divergence, the definition of privacy loss is in fact the definition of $$D_\infty( A(x_1) || A(x_2)) := \max_{S\subseteq {\textbf supp}(A(x_1))} \log \left(\frac{\mathbb P[\mathcal{A}(x_{1})\in S]}{\mathbb{P}[{\mathcal{A}}(x_{2})\in S]} \right).$$
Furthermore, the multiplicative factor $e^\epsilon$ can be -- using a common approximation for small $\epsilon<1$ -- viewed as $1+\epsilon$:
$$e^\epsilon = exp(\epsilon) = 1 + \epsilon + \epsilon^2 + \dots \approx 1 + \epsilon.$$
In less formal terms this definition says that a given result is approximately the same whether it is computed using the first or the second, neighboring database.
A more general definition, that adds flexibility -- but also makes the proofs less elegant and more technical -- is $(\epsilon, \delta)$ -differentially privacy, when
$$\mathbb P[{\mathcal {A}}(x_{1})\in S]\leq e^{\epsilon } \cdot \mathbb P[{\mathcal {A}}(x_{2})\in S] + \delta.$$
Interpreting the definition, the goal of DP is that the risk of violating one's privacy should not substantially increase as a result of either appearing in a statistical database or not. Thus an analyst should not be able to learn any information about a record (i.e. participating an online questionnaire) that couldn't have been learned if one had opted not to participate or answered the questions randomly by rolling a die or flipping a coin rather than answering truthfully.

To overcome the fundamental challenge -- the trade-off between utility of data or accuracy of returned answers and privacy of records -- the set goal is to learn as much as possible about a group's data while revealing as little as possible about any individual within the group. Transforming an algorithm into a DP-algorithm requires probabilistic tools. The sensitivity of a function of $f$ is a good measure of how much statistical noise is needed to mask an answer:$$\Delta f=\max_{x_1 \sim x_2} ||f(x_{1})-f(x_{2})||_{1} = \max_{x_1 \sim x_2} \sum_{i=1}^d |f(x_{1})_i-f(x_{2})_i|.$$Low sensitivity of a function, i.e. small change of output given two neighboring inputs, allows to add statistical noise to achieve privacy yet don't use utility. The Laplace mechanism, adds noise from the Laplace distribution $\mathcal L(\lambda)$, i.e. noise $\eta(x)\propto \exp(-|x|/\lambda)$ which has 0 mean and $\lambda$ standard deviation. Substituting Laplace noise with other probability distributions, such with a 0 mean Gaussian and $\lambda$ standard deviation would be possible, but influences proof details.
A typical construction now is, instead of computing $f(x)$ directly, to compute $\mathcal A(x) = f(x) + \eta(x)$ and obtain a $\epsilon = \frac{\Delta f}{\lambda} $-DP algorithm, since the noise of two neighboring databases doesn't exceed this $\epsilon$ even in the worst-case. In terms of composability, sequential respectively parallel composition leads to a sum of all occurring $\epsilon_i$ resp. maximum of all occurring $\epsilon_i$ differentially private steps within the composed mechanism. This allows to efficiently turn algorithms into DP-algorithm.

These basic construction, including detailed proofs, and much more were covered during the 7th BIU Winter School on Cryptography named "Differential Privacy: From Theory to Practice" featuring speakers, who defined and contributed already roughly 10 years ago to the field. Slides are already online and video recordings about to appear on the webpage.
Furthermore, relationships of DP to various, related scientific fields ranging from statistics to machine learning and finally game theory were explored.

Concluding, in wake of the growing awareness of privacy issues in the digital domain, together with stricter interpretation of legislation and finally the possibility to satisfy most interests by anonymized data anyways; several big players strive to provide differentially private collection of data. Some companies market themselves as quasi-pioneers in privacy topics for some reasons: It pays off to be perceived as the first one; they would be facing various problems in the near future anyways, if they don't respect these issues; and most importantly, they can continue their business model: creating value of user's data. The more information is queried from the database, the more statistical noise has to mask the correct answer in order to meet a predefined privacy budget bound. This total allowed, justifiable privacy leakage can be specified in the number of admissible queries or the answer accuracy.

Provable cryptography avoids the situation of mere obfuscation that can be undone by a clever enough attacker / strategy -- given the security assumption holds -- and provides bounds and thus a guideline on how to choose parameters to guarantee a desired level of privacy. Algorithms invest a given privacy budget at privacy-critical steps. With this in mind, differential privacy is an additional design paradigm for cryptographic algorithms and protocols to keep in mind.

I'd like to end this cryptologic point of view on achieving privacy goals on the internet, as I started; with a fundamental sociological question. One thought that remains standing out is: Shall we collect as much data in the first place? Is it really necessary to predict individuals as online merchants? Do we want this ubiquitous tracking? As with advanced technologies, who's long-term effects cannot be predicted, maybe also in aggregating big data and tracking the only winning move seems to be not to collect data in the first place.

Monday, January 16, 2017

WhatsApp backdoor? Should I be worried?

WhatsApp Backdoor!!! 

Let's start this blog entry with that title and it is very easy to get reader's attention (Especially in the security community) with big bold letters and saying that there is a backdoor. I say this because it was exactly what happened on January 13th (Friday the 13th, maybe it is correlated) when The Guardian released the news. After that, the security community/websites and others started a big debate about it. In fact, some hours after the release from the Guardian others websites started saying that it isn't a backdoor such as: Gizmodo, Open Whisper System blog and others' websites.

Well, we are going to give some "conclusions about the subject" later. First, let's explore more about it.

What is a backdoor?

If we talk about computer systems or cryptography, we are going to have something like this definition: "A backdoor is a method, often secret, of bypassing normal authentication in a product, computer system, cryptosystem or algorithm etc. Backdoors are often used for securing unauthorized remote access to a computer, or obtaining access to plaintext in cryptographic systems." In other words, it is an easy way to obtain access.

Are backdoors common?

Unfortunately, yes it appears in the news and computer systems more than we want. Also, after the Snowden revelations the term backdoor is very common in the non-academic area. However, it does not mean that people become more worried.

What is the real problem?

Perfect, we learned about backdoors. Now, let's explain the problem with WhatsApp. Let's see an hypothetical case, imagine that you have a smartphone and for some reason (fall in a lake, you have been abducted by E.T. and forget your phone in the spaceship) you don't have access to your smartphone anymore. Fortunately, you can recover your phone number, buy a new smartphone and reinstall Whatsapp. However, when you reinstall WhatsApp, it generates a new key. However, now we have a problem what the app should do with the messages that you received when you were offline. The app could just drop the messages and never deliver or it could ask for your contacts to encrypt with the new key. According to the Guardian this approach is the backdoor:
"WhatsApp’s implementation automatically resends an undelivered message with a new key without warning the user in advance or giving them the ability to prevent it."

I, personally, say that it is a mistake that WhatsApp just show a notification saying that the key change and automatically resends.

Is it exploitable?

I will say: Yes, it is.
Let's see how it is possible to exploit.

In fact, it consists in exploit another vulnerability, it is present in the SS7 protocol. The Signalling System No. 7 (SS7) is a set of telephony signaling protocols developed in 1975, which is used to set up and tear down most of the world's public switched telephone network (PSTN) telephone calls. It also performs number translation, local number portability, prepaid billing, Short Message Service (SMS), and other mass market services.

The SS7 vulnerabilities are known since 2008. However, it had the attention from media in 2014, Tobias Engel at CCC showed how it is possible to exploit SS7 vulnerabilities. You can check exactly how in this link. In the video, he shows that it is possible to change the phone number between cellphones. In the same congress and right after Tobias, Karsten Nohl showed how to read "others SMS", the talk can be followed in this link.

What is the SS7 vulnerability?

Let see very quickly the structure of a GSM network, the next figure shows it.


So, if you are inside of the SS7 network, you can just start listen the network and as we saw in the videos it is possible to change somethings such as your number.

Since it is possible to change your number and the verification from whatsApp can be done by call or a SMS verification. What happened if I have access to SS7 network and change my number to any other number and I reinstall WhatsApp and pass the verification?

According to the policy of WhatsApp, my smartphone is going to generate a new key and all the new messages are going to be encrypted with this new key. I didn't create a new attack here, it has been done before as this youtube video shows:


It is valid to say that this attack can be used in others messengers. However, others apps have another policy, e.g.  Signal drops the messages until you "recheck" the new key.

 If you are interested to see the how messengers handle this key problem, there is a nice blog entry at Medium.

Conclusions? 

The news from Guardian is not a real backdoor, it is a known problem about handling with keys and the news was more like a "click bait". However, the good thing about all of this history are the discussions in different communities and an alert to people take care about their privacy.

All this incident makes us to start doing some social and technical questions, such as:
Should we accept the news from the media as truth?
Why the hell we continue to use a system from 1975?
Can we create a better way to handle with keys?


 In addition, I should say that if you are looking for more privacy to your life. You should check Privacy Tools, in this case, the section about "Encrypted Instant Messenger".
 

Tuesday, September 6, 2016

Requirements and security goals for the Cloud

This is a two-part blog post giving an overview on the requirements and security goals for the Internet of Things (IoT) and the Cloud.

But first ... I'd like to mention that soon the ECRYPT-NET Summer School on cryptography for the cloud in Leuven is coming up.
This blog post can be seen as an intro to cryptology in the cloud; so there are some topics we will for sure hear about at the event in depth. I'm looking forward to a good discourse during the scheduled talks and to the discussions afterwards.

Part I: Requirements and security goals for the Cloud


The cloud here is loosly defined as computing and storage resources out-sourced to servers located off-site that are on-demand accessible via Internet.

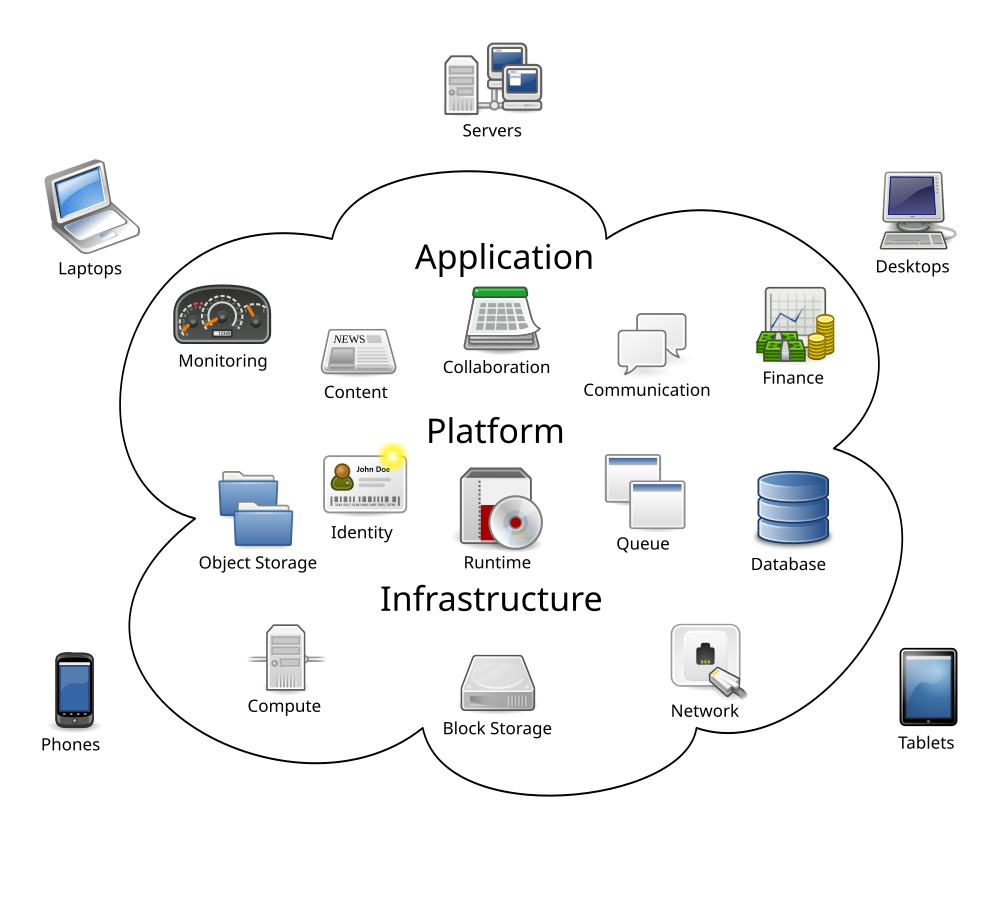
Overview of cloud computing services to be secured
(Image by Wikimedia user Sam Johnston)
The usage of cloud services should thus be viewed as a potential threat, because inherently critical data is released from personal control and uploaded and so immediately raising several security as well privacy issues.

Requirements and the according cryptologic counter-measures are defined for various use-cases (such as depicted in the image) and briefly explained. It is important to realize that this needs to be done without deliberately weakening (or "back-dooring") solutions, as is sometimes suggested. To ensure democratic use of the developed technologies it is vital to see that the difference of a "front door" and a "back door" is merely ones viewpoint. Intentionally implementing two entrances makes an attacker happy not the legitimate user.

Transparent services, meaning the use of the cloud as if it was on-site, should ideally be built upon a back-end with verifiable, clear, possibly standardized, cryptologic concepts and open code for public scrutiny.

To capture the real-world cloud settings one has to view it from different perspectives: First the one of a private entity (user), then that of an organization (such as a company) and lastly the global perspectives of, say, a government.

An interesting starting-point for threats we have to consider, is the Cloud Security Alliance's 2016 report for cloud security naming twelve critical issues ranked by severity of real-world impact.

Data breaches is followed directly by weak identity, credential and access management and insecure Application Programming Interfaces (APIs) in this report --- issues that can be addressed by assessing requirements and tailoring cryptographic solutions from the beginning and deploying state-of-the-art implementations instead of sticking to legacy code.


Roughly four categories of requirements for the usages of the cloud can be distinguished:
  • Computations in the Cloud
  • Sharing Data in the Cloud
  • Information Retrieval from the Cloud
  • Privacy Preservation in the Cloud
The approach to secure these areas are manifold. General speaking, while data minimization is a fundamental paradigm for efficient interaction with the cloud security-by-design --- considering best-practices from the beginning --- is enabled by encapsulation of scopes of methods.
The following, briefly explained, concepts tackle concrete use-cases for end-users, companies and e-Government tasks alike:
  • Order-Preserving Encryption (OPE) allows efficient range queries but does it diminish security too much?
  • Format-Preserving Encryption (FPE) offers in-place encryptions in legacy databases.
  • Data De-Duplication (DDD) is enhancing servers' back-end performance.
  • Secret Sharing Schemes (SSS) is solving back-up and availability issues by distributing encrypted parts of the whole.
  • Malleable Signature Schemes (MSS) is providing flexible authentication for documents and derived data.
  • Private Information Retrieval (PIR) privately accessing elements in a database.
  • Provable Data Possession (PDP) ensures that the cloud is storing the (uncorrupted) files.
  • Multi-Party Computation (MPC) allows secure cooperation across the Internet.
  • Verifiable Computation (VC) builds trust in results of a delegated computation.
We can observe that the cryptology community is striving for efficient cryptographic primitives that serve as building-blocks for implementations. Naturally researchers base their constructions on well-established security assumptions and derive clear security proofs to offer i.e. long-term confidentiality. This is not at least important because of the emergence of future quantum computers with powerful quantum algorithms posing a threat and needs to be addressed today before the transition of current solutions to the cloud, where the constructions would be exposed and would possibly be vulnerable to a quantum attacker.

Let's hope this trend continues and ultimately leads to reliable, standardized primitives for real-world applications.


Stay tuned for Part II: Requirements and security goals for the IoT...

Sunday, December 13, 2015

Post-Snowden Cryptography (PSC - Brussels)

On December 9 and 10, the Post-Snowden Cryptography Workshop took place in Brussels. The main topic of the discussion was cryptography and privacy after the revelations from Edward Snowden.


Day one

In the first day of the workshop, we learned about Qubes OS and how it works from Joanna Rutkowska. In the second talk, Kenny Paterson presented some disturbing facts about the NSA's capabilities from Snowden's revelations such as a rumoured "real-time breakage of RC4" and "ability to break certain unnamed VPN products". Also, he gave some solutions for the new problems of surveillance such as building cryptographic implementations that are "strong, fast and developer-friendly." Next, Phil Zimmermann gave a speech and answered questions. In the last talk of the first day, Jon A. Solworth presented the Ethos Operating System and how his group built the OS. He explained some important features of the OS such as how its networking is "encrypted, cryptographically authenticated, and authorized."


Day two

On the second day, Christopher Soghoian spoke about the revelations of the NSA and how the FBI uses this information, i.e. how law enforcement is the "little brother" that does the actions. Claudia Diaz presented some results about website fingerprinting on Tor, i.e. how to collect information from a client that is using Tor. Website fingerprinting consists of recognizing the traffic patterns of specific web pages without other information. Ian Goldberg presented DP5. DP5 allows clients to register and interact with friends without leaking metadata.

Next, Christian Grothoff talked about the development of GNUnet and how it is built. One little part of the work, i.e. the complexity of the development of any library he presented a dependency graph of GNUnet. Then, in the last part of the workshop, Jacob Appelbaum presented a "modest post-Snowden proposal." In fact, the correct term is post-Snowden revelations, since Snowden is still alive. In this talk, he presented a different view of the situation, that is, we did not need to hide the information. In the last talk of the day, Nathan Freitas presented an overview of the Guardian Project and his experience with development of secure apps for Android. He showed that the Guardian Project has SDKs for encryption in mobile applications such as SQLCipher to encrypt databases.
The event presented an ethical view of cryptography and which path cryptography is following. The moment for this discussion could be reached in better time, after the essay from Phillip Rogaway called "The Moral Character of Cryptographic Work," cryptographers need to pay more attention in their work. In simple words, this means that we should care about what we are doing and how this will impact society. We need to ask ourselves what kind of legacy we want to leave behind or what benefits we want to bring to the world in general.

Slides for some speakers' talks are available on the Post-Snowden Cryptography Workshop website.

Videos

The videos of the talks are available: https://psc2015videos.projectbullrun.org/

Monday, November 30, 2015

Privacy Preserving Authentication for Lightweight Devices

Welcome again, dear reader!

I have recently read "End-to-end Design of a PUF-based Privacy Preserving Authentication Protocol" by Aysu et al. which was published at CHES 2015.
They have designed and implemented a complete protocol for authenticating lightweight devices and include a security proof.
I would like to start by pointing out their definition of privacy:
A trusted server and a set of [...] deployed devices will authenticate each other where devices require anonymous authentication. [...] Within this hostile environment, the server and the devices will authenticate each other such that the privacy of the devices is preserved against the adversary.
So they are protecting the privacy of the authenticating devices against an adversary but not against the server to whom they are authenticating! If your background is in public key crypto or if you consider internet technologies this might seem surprising. After all, can't we just establish a secure channel to the server and an eavesdropper or man-in-the-middle will never learn anything?
Of course, it turns out the situation is not so simple:
  • Even if you use public key crypto you have to be very careful. In 2014 a paper by Degrabiele et al. showed how to fingerprint Australian health care cards using only ciphertexts encrypted with a card specific public key. Here is an explanation of the issue. The problem is that they used RSA which does not offer key privacy. Key privacy is the property that given a ciphertext and a set of public keys it should not be possible to determine which key was used for encryption.
  • For RFID tags it is actually often assumed that public key crypto is not possible at all. It is either too expensive (in terms of hardware) or too slow. One standard for e-ticketing, for example, requires a response time of less than 300 ms [source].
That the authors consider a symmetric system is also obvious by the extra capabilities that they grant their adversary:
The malicious adversary can control all communication between the server and (multiple) devices. Moreover, the adversary can obtain the authentication result from both parties and any data stored in the non-volatile memory of the devices.
Of course, if you want to use symmetric crypto you need to make sure that an adversary cannot just extract the shared key from a device.

And that is what the authors are tackling in this paper and where there adversarial model comes from!
Their solution to the problem involves another interesting invention, so called physically unclonable functions. These use properties of the hardware to create a function which can only be calculated on one device. Usually this is done by using some more or less random physical properties, like the initial contents of a memory chip after it is powered on, which are then post-processed so that outputs from different devices are random but the output of the same device is reasonably consistent.

With the help of physically unclonable functions the device and the server can derive a new shared secret for each session but the secret cannot be extracted from the device! Awesome.